AI Optical Character Recognition Tool
Introduction
The AI Optical Character Recognition Tool is a deep learning-based visual optical character recognition tool that supports custom labeling and inference for different characters. By completing the wizard-style configuration process, users can quickly implement the full workflow from image acquisition to deep learning inference. This tool is typically used in scenarios that are difficult for traditional algorithms to handle, such as metal engravings, characters on curved surfaces, and complex backgrounds.
This tool has a built-in pre-trained model. After setting the target region, you can perform inference directly without training from scratch. As needed, use additional training to optimize the model based on the inference results.
-
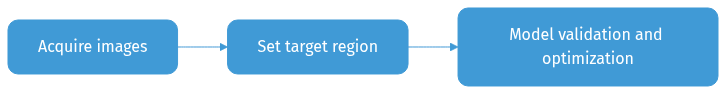
Acquire images: Acquire image data for validating and optimizing the model. It is recommended to cover typical conditions in the actual production environment to ensure image quality and diversity and improve deep learning inference accuracy.
-
Set target region: Set the target region on the acquired images. Supported shapes include the entire image, a rotatable rectangle, and a ring. This limits the character recognition range and reduces the impact of irrelevant areas on inference results.
-
Model validation and optimization: Use the acquired images to validate the model’s recognition performance. As needed, configure character correction, recognition range, judgment conditions, and string concatenation rules. If recognition results are inaccurate, use Additional Training to add images and optimize the model for specific cases until it meets actual requirements.
Usage Workflow
After entering the tool, click the New button in the upper right corner of the model list on the left to create and enter a new model configuration process.
Acquire Images
Acquire image data for inference and model optimization.
-
Confirm that the input port for the current step is connected to the image data.
-
When you enter the tool, the camera automatically acquires an image for model validation. Click Single Capture to acquire another image for model validation.
|
When acquiring images, it is recommended to cover typical variations in the production site, including:
Diverse images help validate the model more comprehensively and improve the efficiency of subsequent optimization. |
Set Target Region
After acquiring images, set the target region to define the character recognition range and reduce the impact of irrelevant areas on inference results.
|
When the Object Pose port has input, the target region transforms along with the target pose. The target region set here is the reference position; during recognition, it shifts dynamically according to the alignment parameters. |
-
Click Edit to open the target region settings.
-
Set character size.
The system will automatically generate an orange default character size rectangle in the visualization area. After selecting it, you can adjust its size by dragging the border. To ensure model inference accuracy, please adjust this box to a size close to the actual character size. Too large or too small will affect recognition performance.
If the character size region is not displayed in the visualization area, check whether the Show character size region switch is enabled.
-
Set the target region. Two methods are available:
Setting method Description Set all as the target region
The target region automatically covers the entire image. Suitable for scenarios where the target characters fill the image. To exclude certain areas, set mask regions in the next step.
Custom target region
Select the "Rectangle" or "Ring" selection tool and drag in the visualization area to draw the target region. Accurately select the area based on the actual position and shape of the target characters, avoiding irrelevant backgrounds.
-
Rectangle selection: Drag directly to draw a rectangular ROI.
-
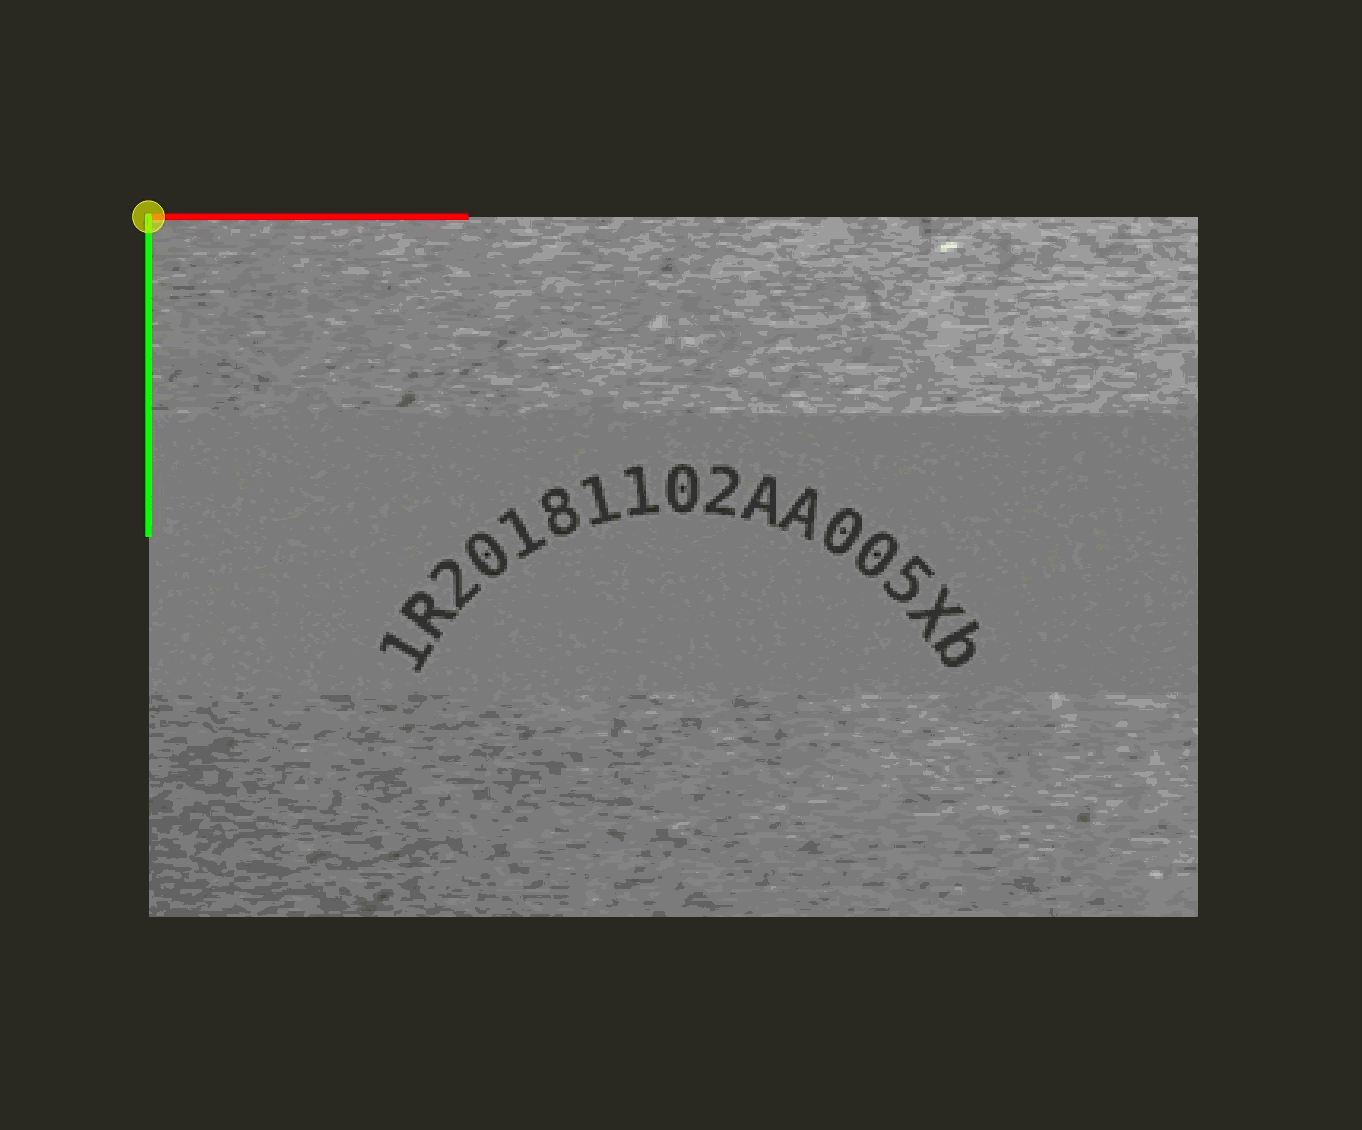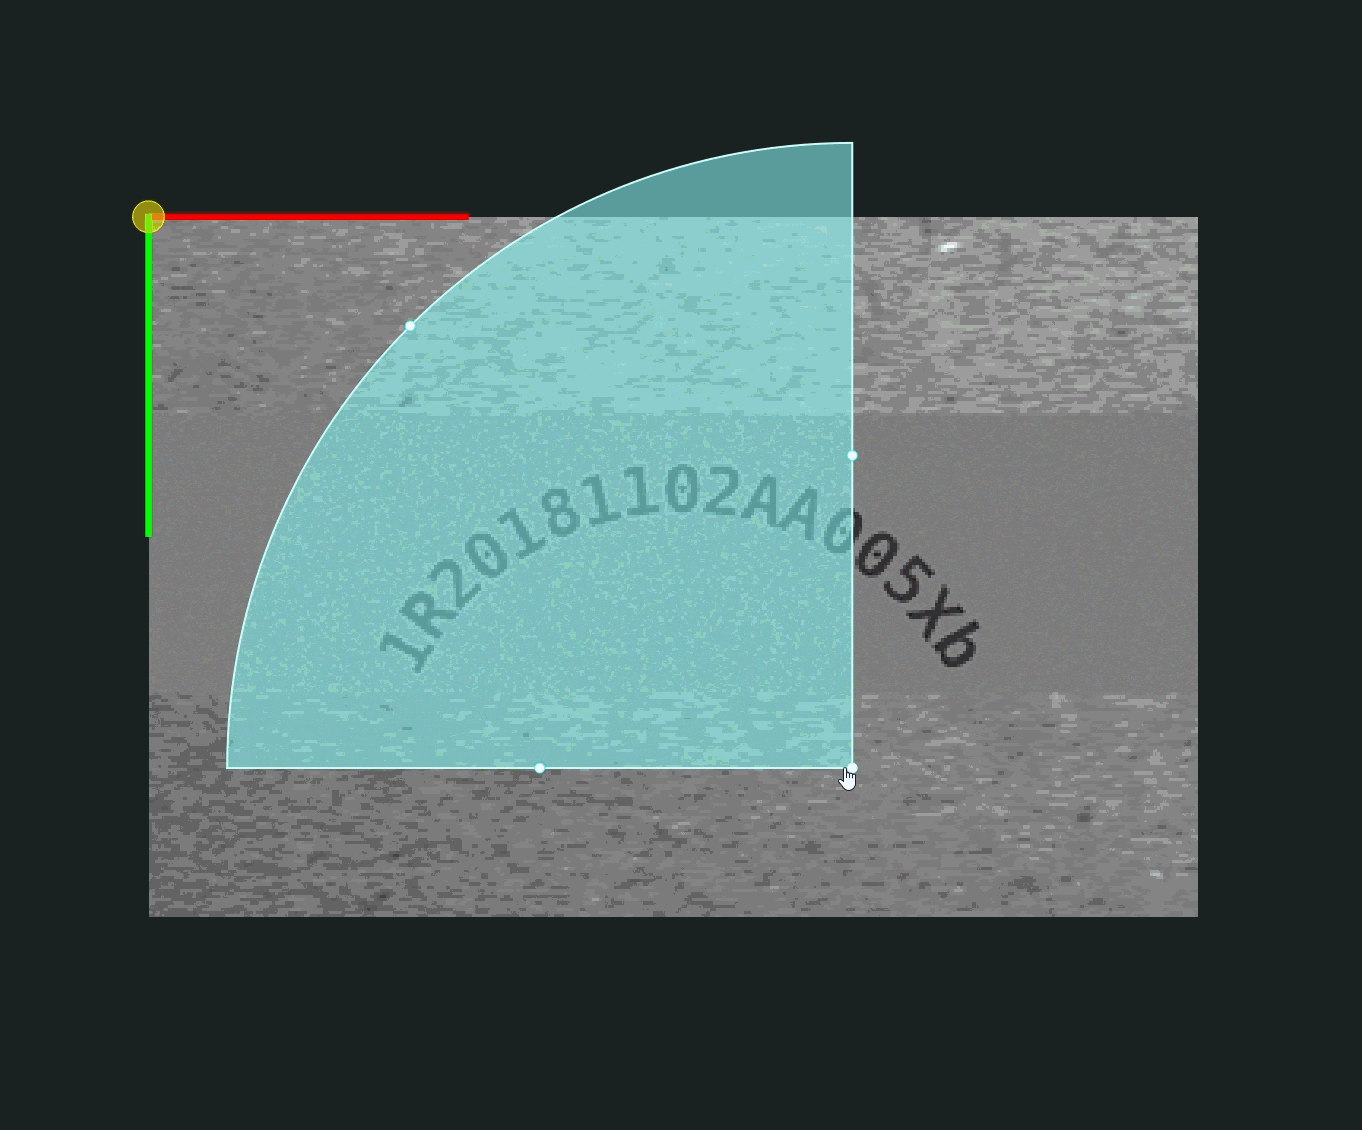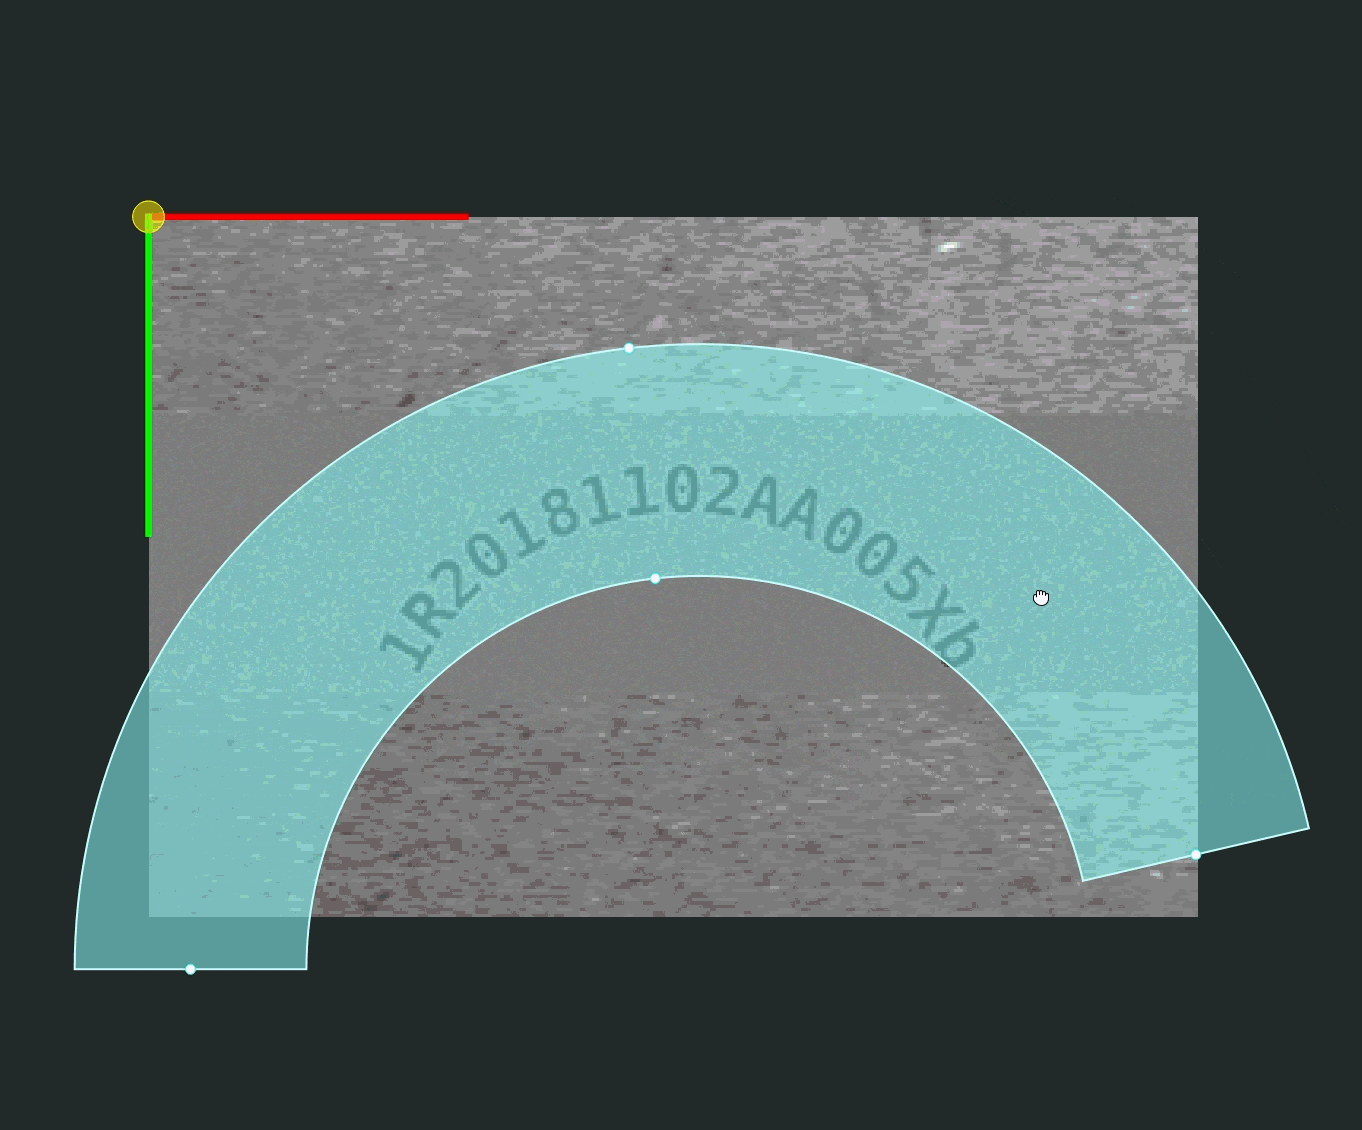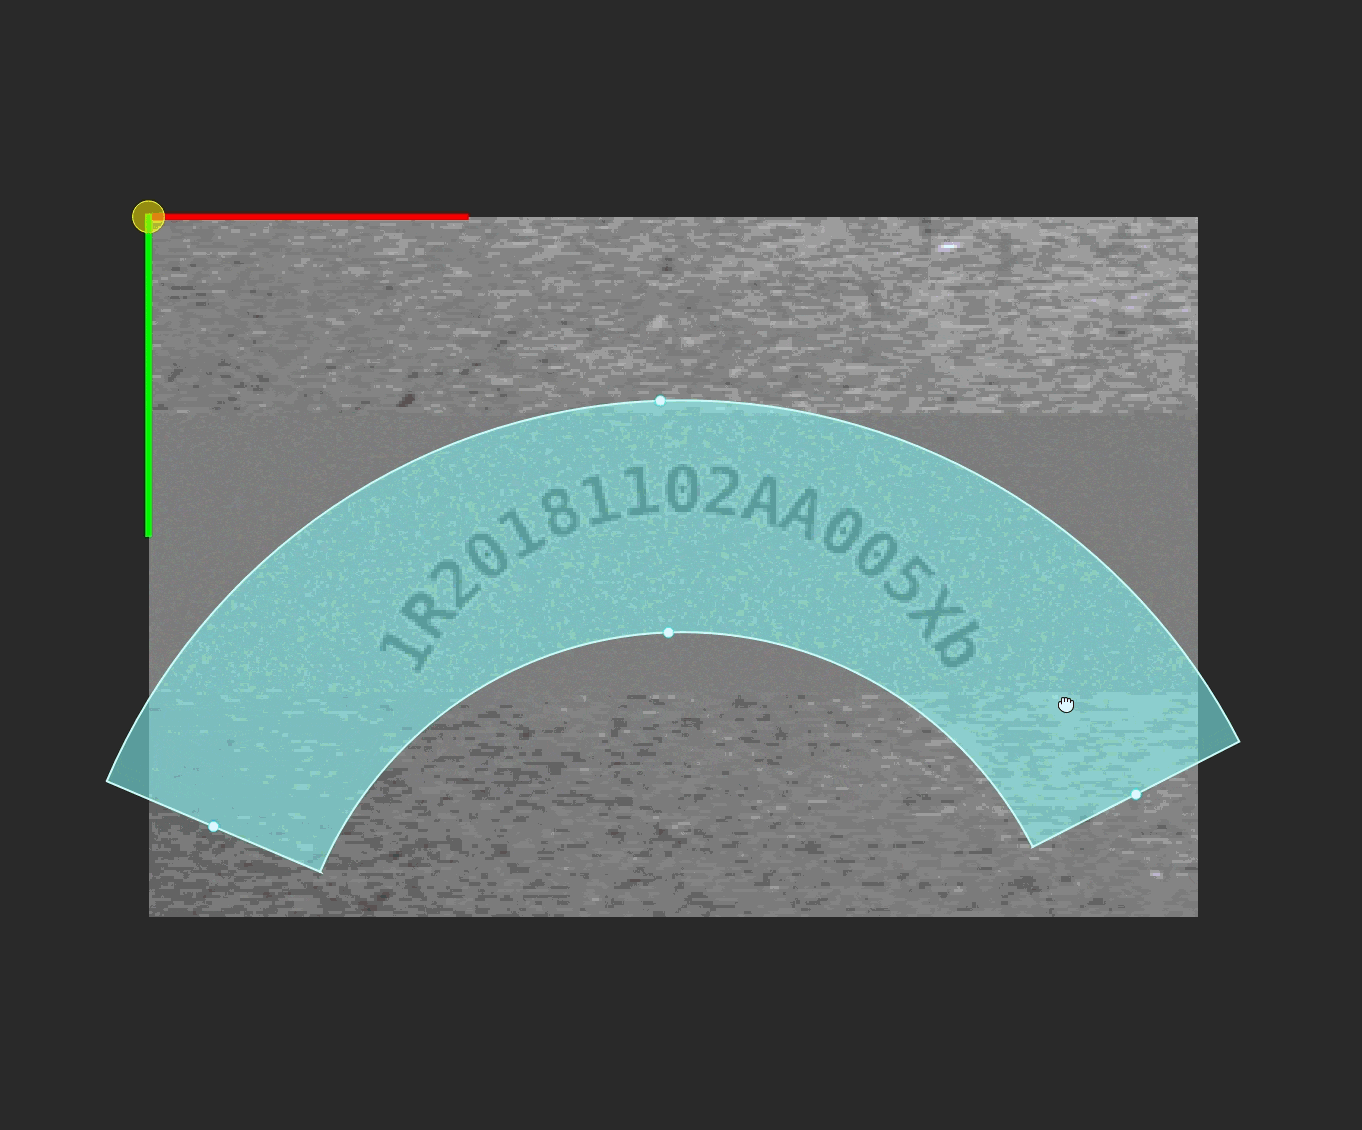
Ring selection: Refer to the image below to drag along the circumference to draw a ring ROI. After drawing is complete, you need to set the reading direction of the circular text to clockwise or counterclockwise.
-
-
Set mask region (optional).
When there are irrelevant interferences such as reflections, shadows, or fixed backgrounds within the target area, you can set mask regions to exclude them, avoiding impact on model training and classification judgment results.
Click the Set mask region button, and use the "Polygon" selection tool to draw the mask region in the visualization area: click the left mouse button to add polygon vertices, then click the right mouse button to close the polygon and complete the selection.
-
Save the target region settings.
After setting the target region, click Save and apply to apply the settings.
|
When the masks of the character size region, target region, and mask region completely overlap, only the topmost layer can be edited. |
Model Validation and Optimization
After completing the steps above, use inference images to validate the model. Configure inference rules or perform additional training as needed.
View Inference Results and Configure Inference Rules
Click Single Capture and Inference to view the current model’s inference results and check whether they meet expectations.
+ If the inference results are generally correct but the judgment rules do not meet actual needs, adjust the judgment criteria by configuring inference rules to improve the accuracy and applicability of the results.
+ After you change the inference rules, the tool updates the model based on the current rules and performs inference on the current image. You can view the result above the parameter configuration area.
| Parameters | Description |
|---|---|
Inference result |
Parameter description: Displays the character recognition result. When judgment is enabled, the result is displayed as OK or NG according to the configured judgment conditions. |
Time |
Parameter description: Displays the single inference time (unit: ms). |
Current image confidence range |
Parameter description: Indicates the confidence range of all character inference results in the current image.
|
Character correction |
Parameter description: Used to constrain the types of the first N characters in the recognition result. The number of wildcards entered determines the number of character positions constrained; subsequent characters beyond this length are not affected. When a character at a certain position does not match the constrained type, the model will replace it with the candidate character with the highest confidence of that type. Supported wildcards: ? (any character), $ (letter), % (number), @ (symbol), ! (uppercase letter), & (lowercase letter). Default value: Off. Tuning instructions: Suitable for fixed-format character correction, such as scenarios where the first few positions have clear type requirements. It is recommended to fill in wildcards from left to right according to the actual encoding rules, avoiding over-constraining that may cause incorrect replacements. Tuning example: It is known that the actual encoding format is "number + uppercase letter + number + ...", but the model recognition result is iR20181102ar06Xd", where the first character was incorrectly recognized as a lowercase letter. 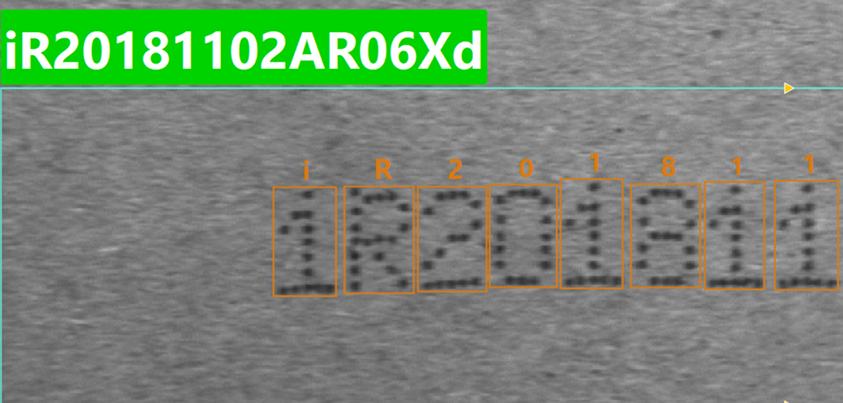
In this case, enter "%!%" in the input box (the 1st position is constrained to a number, the 2nd position is constrained to an uppercase letter, the 3rd position is constrained to a number; the 4th position and beyond are not constrained). After re-inference, the first character is corrected to the number with the highest confidence, and the result becomes "1R20181102ar06Xd". 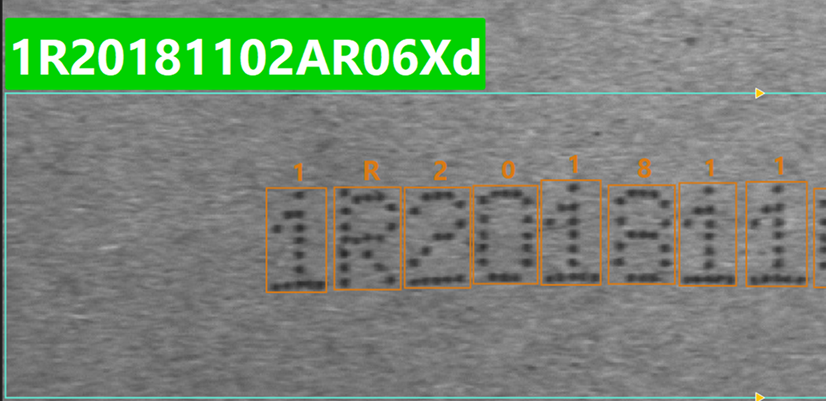
|
Recognition target |
Parameter description: Used to specify the character types to be extracted from the recognition results for further processing. Unselected character types will be ignored.
|
Insert separator |
Parameter description: When multiple lines of characters are recognized, this parameter is used to specify the separator to join segments for the final output.
|
Enable judgment |
Parameter description: Used to check whether the recognition result meets expectations. You can specify character types, character count, or a fixed format. Results that do not meet the rules are judged as NG. Two judgment modes are supported:
Default value: Off. Tuning instructions: Use this for automatic compliance checks. Select manual input mode to validate fixed formats, or global variable mode to validate dynamic content. |
Additional Training (Optional)
If the inference results are still unsatisfactory or the model does not cover certain typical cases, use Additional Training to make targeted corrections until the model meets actual requirements. Common issues include:
+
-
Character misrecognition: For example, "A" is recognized as "4", or "0" is confused with "O".
-
Missed characters: Some characters are not detected.
-
Background false detection: Non-character areas, such as logos, textures, or reflections, are incorrectly recognized as characters.
+ When these issues occur, add recognition content or exclusion content as appropriate.
+ Add additional content based on the problem type:
+
| Additional content | Description | Operation |
|---|---|---|
Recognition content |
Used to correct missed or misrecognized characters. Draw a box around a character that was not correctly recognized, enter the correct character for that position, and add it as training content. |
|
Exclusion content |
Used to eliminate background false detections. Draw a box around an area that was incorrectly recognized as text and mark it as an ignore region. Recognition results in this region will be removed. |
|
+
|
At this point, the model configuration is complete. After closing the tool window, select the model from the Model Name parameter drop-down list to use it for character recognition in subsequent inference Steps.